Your AI content watermark isn’t what Google is looking for


Anthropic’s new invisible watermark for Claude-generated text sounds like a problem for SEOs using AI to create content at scale. It isn’t.
Google doesn’t penalize content simply because AI was involved. What matters is whether the page adds something useful, original, and valuable for searchers.
What Anthropic’s AI watermark actually does
On Aug. 11, Anthropic confirmed that Claude’s text now carries an invisible watermark. Every model it has released since Aug. 2 marks its own output.
A model writes by picking one word at a time from a list of plausible next words, and the watermark quietly biases that choice toward a secret half of the vocabulary.
No single sentence looks odd, but across a few hundred words, the bias is measurable by anyone holding the key.
Where the mark lives is what makes it interesting. It isn’t metadata sitting on a file, the kind of thing a CMS strips on upload. It’s the word choice itself, so it travels with the text.
Copy it out of the chat, paste it into your CMS, and the signature comes with it. You can’t see it, and you can’t easily strip it out.
Anthropic isn’t acting alone. The EU AI Act’s transparency code took effect on Aug. 2 and requires AI-generated content to be marked so other systems can identify it. Every other lab is under the same obligation, and with the backlash against AI slop building, expect marking to become more common.
If you’ve spent three years using ChatGPT, Gemini, and Claude to produce blog posts, service pages, and category descriptions at scale, the obvious thought is:
- “Google is going to find the mark, flag the pages, and my traffic is going to disappear.”
The watermark is real, but Google doesn’t penalize content for being written by AI.
Dig deeper: If an AI watermark scares you, your content may be the real issue
What Google actually said
Let’s start with what Google has put in writing. In February 2023, Google published its position on AI-generated content. The core line:
- “Appropriate use of AI or automation is not against our guidelines.”
And on whether it helps you rank:
- “Using AI doesn’t give content any special gains. It’s just content.”
Content is just content to Google. Rather than play detector against generator, it understood the arms race it would be signing up for, and it was unusually well placed to lose it, given it wrote much of the foundational research the current models are built on.
So it didn’t draw a line at how a page was made. It drew the line at whether a page adds anything a searcher would find valuable.
The same logic runs through the spam policies, which are the rules a manual action gets issued against. There are 16 of them. Generative AI appears twice in the entire document.
Once to note that people try to manipulate AI features, so the spam rules cover that, too. The second time is the one that matters, inside scaled content abuse:
- “Scaled content abuse is when many pages are generated for the primary purpose of manipulating search rankings and not helping users.”
And, in the same policy:
- “[C]reating large amounts of unoriginal content that provides little to no value to users, no matter how it’s created.”
Google had already made that comparison itself in the same February post:
- “About 10 years ago, there were understandable concerns about a rise in mass-produced yet human-generated content. No one would have thought it reasonable for us to declare a ban on all human-generated content in response.”
A hundred human freelancers churning out thin pages breaks that rule exactly the way a prompt loop does. The pattern is the problem: many pages, no added value, built to move rankings.
What it looks like when someone actually does it
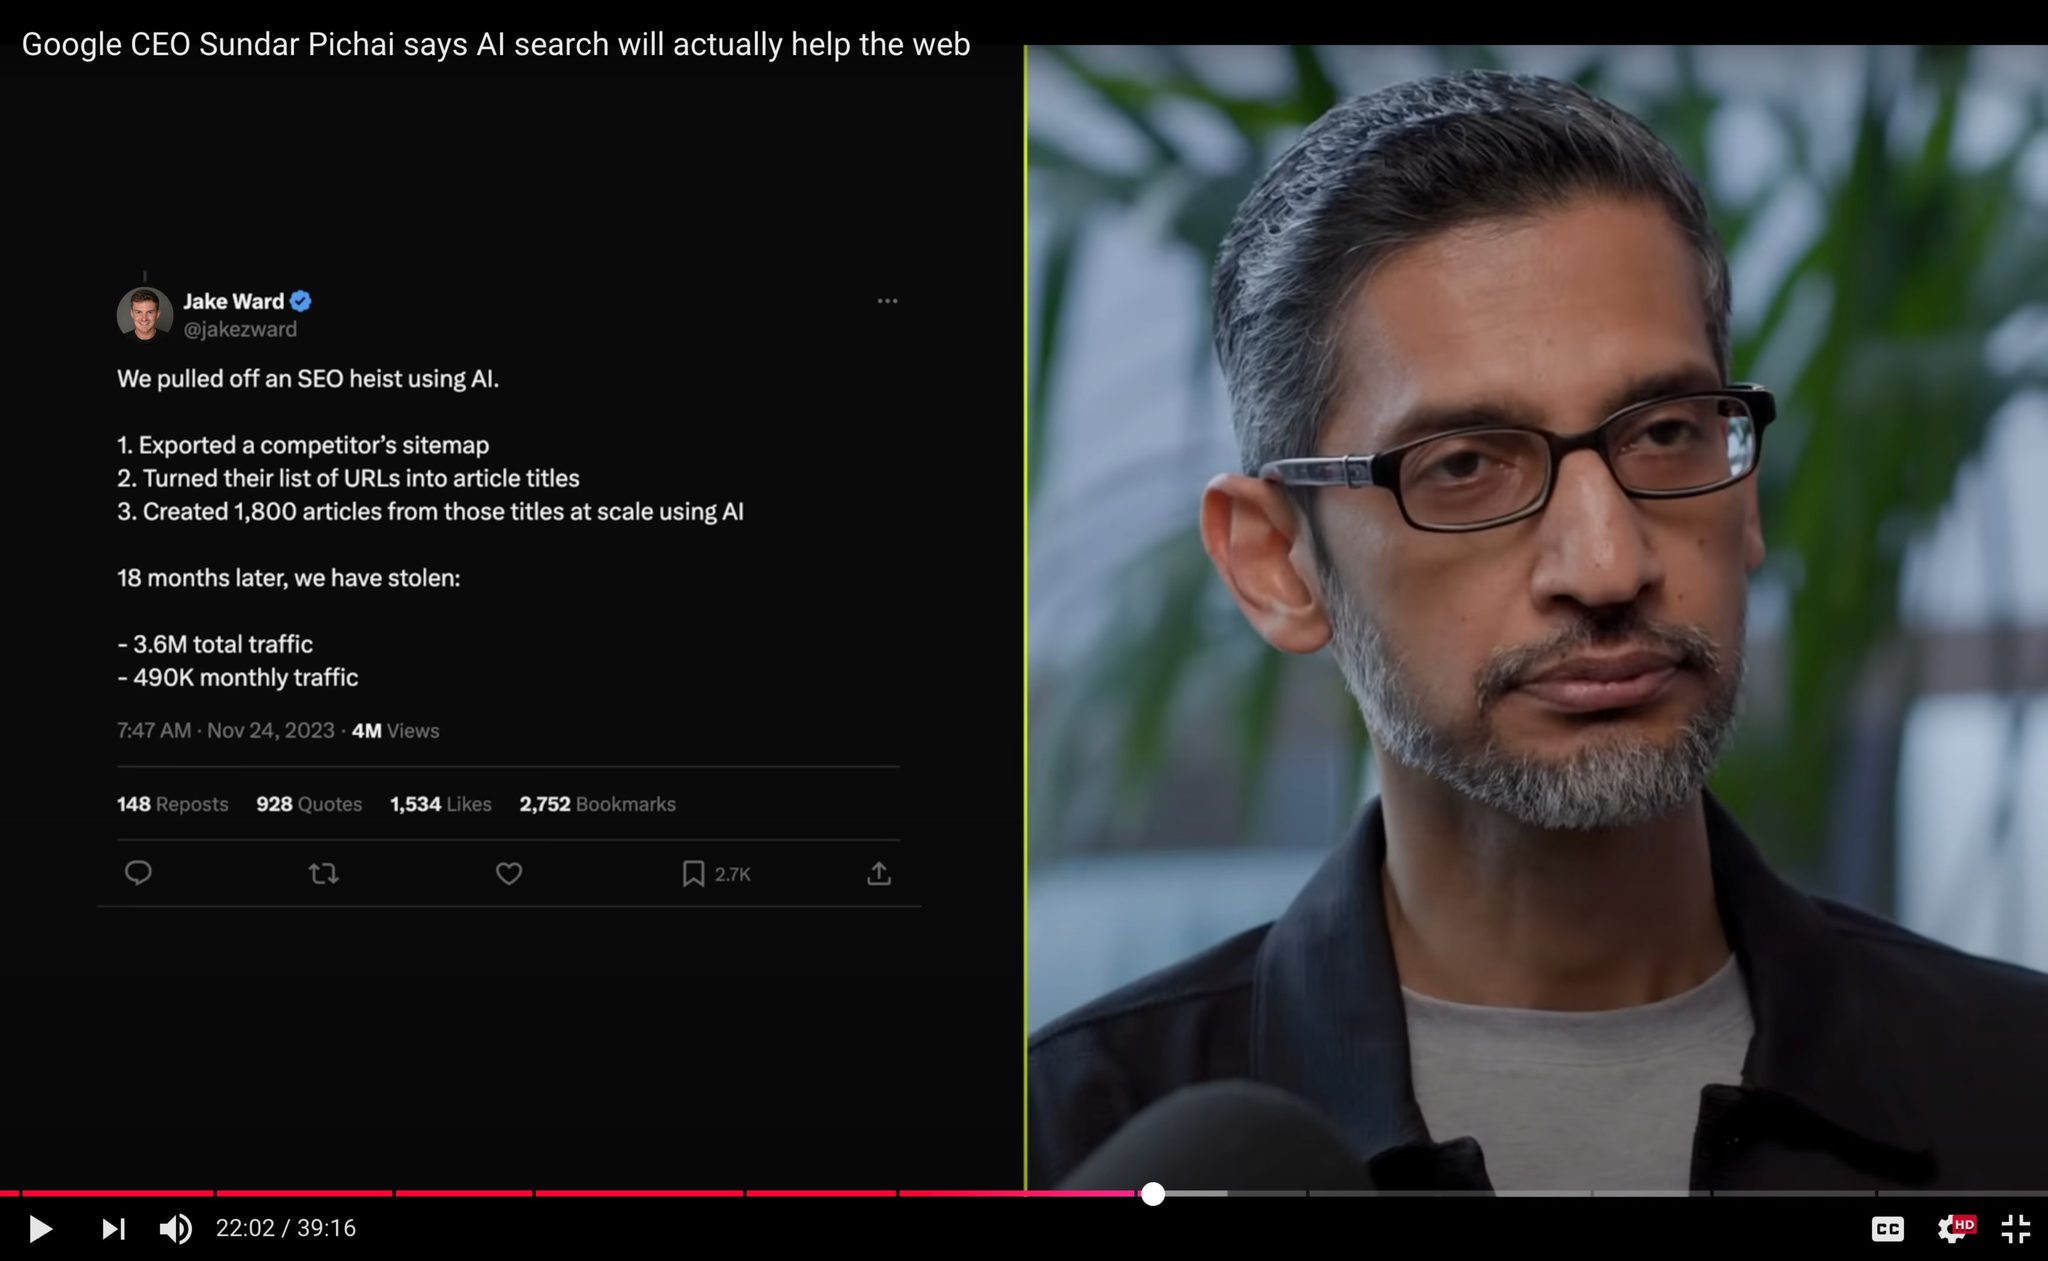
Here’s what the AI content play looks like at full tilt. In November 2023, an SEO founder called his experiment an SEO heist.
He’d exported a competitor’s sitemap, turned that list of URLs into article titles, and generated roughly 1,800 articles from them at scale.
He published the running total: 3.6 million visits in all, 490,000 a month, taken from the competitor. The post did 4 million views.
Search Engine Land told the full story, and it eventually reached Google CEO Sundar Pichai, who was shown the tweet on camera and asked about it.
Then it came apart. Within months, the gains had largely evaporated, and the site sat back around where it started, if not worse.
Hold it against the policy: many pages, no added value, built to manipulate rankings. Three for three.
That’s why it got hit, and why the other sites running the same playbook got hit alongside it.
Now the study that looks, at first glance, like it proves me wrong. Semrush graded 42,000 blog posts with an AI detector and sorted them by ranking position. At Position 1, pages came back 80.5% likely to be human-written and only about 10% likely to be AI.
Human content took the top spot roughly eight times more often. Read that as “AI can’t rank,” and you’ve misread it, and the researchers said as much themselves.
The detector reads the finished product compared with the process it was created from.
A page that somebody genuinely worked on reads like one, even if a model helped draft it.
The same study notes that AI is now a standard part of production for most teams, and that from position five downward, the gap between human- and AI-classified content is narrow.
It isn’t that AI can’t rank. It’s that laziness can’t hold the top of the page. The watermark doesn’t change that in either direction.
Dig deeper: How AI-generated content performs in Google Search: A 16-month experiment
What Google actually rewards
So if AI isn’t the problem, what is Google rewarding? There are a few things, and none of them has anything to do with who typed the words.
Effort
The first one is written publicly in the Search Quality Rater Guidelines.
These are the instructions Google gives the people who assess search results by hand. Rater scores don’t directly affect rankings, but the guidelines tell you what Google is training its systems to prioritize. Section 3.2 covers how to judge the main content on a page:
- “For most pages, the quality of the MC can be determined by the amount of effort, originality, and talent or skill that went into the creation of the content.”
And then it defines the first of those:
- “Effort: Consider the extent to which a human being actively worked to create satisfying content.”

The definition goes further. Google says effort “may go into designing page functionality or building systems that power a webpage,” and gives the example of a page offering machine translation as a service.
A calculator you built counts as effort, even though a machine does the work once it’s live.
Then comes the counterexample, which reads like the SEO heist described before it happened:
- “[T]he automatic creation of thousands of pages by running existing freely available content through existing translation software without any oversight, manual curation, etc., would not be considered to have effort.”
So that’s it. The line doesn’t fall on who wrote the words, but on whether anyone was paying attention.
Commodity vs. non-commodity content
Effort is the principle.
The useful test sits underneath it, and Google has started saying it in blunter language.
In April, at Search Central Live in Toronto, Google’s Danny Sullivan put up a slide that split content into two columns, commodity and non-commodity, and asked the room to work out which side their own blog sat on. His definition of the good column was three words: unique, specific, and authentic.
Unique enough that others can’t easily replicate it, specific to a real instance rather than a general rule, and authentic in that it shows firsthand experience.
The examples made it concrete.
- For a running store, the commodity post is “Top 10 Things to Consider When Buying Running Shoes.”
- The non-commodity version is “Why This Customer’s Shoes Collapsed After 400 Miles,” a breakdown of how one runner’s gait caused the foam to fail.
- For a real estate agent, commodity is “7 Tips for First-Time Homebuyers.” Non-commodity is “Why We Waived the Inspection and Saved $15,000,” the agent explaining they crawled the sewer line themselves and saw it was PVC, not concrete.
- For an interior designer, commodity is “Kitchen Trends You Need to See.” Non-commodity is “Why I Refused to Install Marble for a Family of Five,” with the grape juice and turmeric stain tests that proved the point.

The commodity post could have come from anyone or any model. The non-commodity post could only have come from the person who was actually there.
Sullivan was careful to say commodity content is sometimes exactly what a page needs.
Information gain and the patent behind it
None of this is new thinking at Google. It has a name and a patent: information gain.
The Google search patent filing, “Contextual estimation of link information gain,” scores a document on:
- “[A]dditional information that is included in the given document beyond information contained in other documents that were already presented to the user.”
In plain terms: If your page says what the other 10 results already say, it doesn’t matter how clean the prose is or who wrote it. It adds nothing, so it struggles to rank, and if it’s already ranking, it decays over time.
(Semrush has a good plain-English breakdown if you want the longer version.)

Which leaves one question worth asking, and it’s a mindset shift more than a technique.
Before you publish a page, ask yourself honestly: “Is this genuinely useful, is it unique, and is it valuable?”
If you can answer yes, an AI watermark isn’t your problem.
The industry’s trusted source for essential news and analysis.
Sign up for our newsletter to receive exclusive insights and updates directly to your inbox.
- Daily breaking news
- Expert analysis from industry veterans
- Join over 200k subscribers
- Covering SEO, PPC and AIO
How to make your content non-commodity
So how do you get to yes? Here are three easy things you can work on.
Whether a model drafted the page or not, each one makes sure it offers something the other 10 results don’t.
1. Put something on the page that took real effort
The cleanest example is an interactive tool.
A calculator is proof of effort a model can’t fake from a prompt — a tax estimate on an accountant’s site, a sizing quiz on an ecommerce store, a repayment tool on the agent’s.
You can build one with AI in an afternoon now, which is exactly the point.

It doesn’t have to be handwritten. It has to exist, and it has to do something the 10 blue links can’t.
2. Stop publishing only text. Make the visual.
A page that’s only words competes with every other page of words on the topic.
A short video or an original chart built from your own data is a format most competitors never bother with, and it’s far harder for a model to mass-produce.
So write the article, then film the short version and cut it into clips, or turn your data into a diagram nobody else has.
We’re doing exactly this, filming video to sit inside older blog articles so a visitor can read or watch.

Original infographics and charts count, too, as long as the data inside them is yours.
3. Put in something only you know
This is the non-commodity column, applied to your own desk.
Your own numbers, from your own work, or a view you’d defend from your own experience.
Buffer has been doing this since 2013. They publish their salary formula and every individual salary, alongside a live revenue dashboard that anyone can read.
No competitor can reproduce those pages because the content is Buffer’s own books.
It was never a clever keyword play. It’s a page that exists because they were willing to publish something nobody else could. You don’t have to go that far.
A plumber who replaced 400 hot water systems last year knows which brands come back for repairs and how long they really last. Nobody on page one has that because nobody else has the job book.
An ecommerce brand knows which styles get returned and what customers type in the reason box, which is a sizing guide no competitor can copy.
You don’t need to name the client or reveal anything confidential.
The specifics just have to be true, concrete enough that a reader can tell you were in the room.
Then put a real name and face on it, an author with stated credentials, because most articles ship with no byline at all, and that tells Google and the models nothing about who stands behind the page.
Dig deeper: Use Claude for SEO. Don’t let Claude do SEO.
So what does Google penalize?
Google penalizes pages produced at scale that provide little or no value and are intended to manipulate rankings.
The people getting caught pushed too hard, too fast, with content that added nothing, and the watermark had nothing to do with it. The watermark is a provenance mark.
It answers, “Was a model involved?” — a question Google’s ranking systems decided years ago they don’t rank on.
Where it actually bites is one layer up, at the platform. LinkedIn now offers readers a “Seems like AI slop” option for reporting a post.
That’s a trust and reputation problem that every platform is facing.

Don’t burn effort scrubbing it out of your pages to satisfy a search penalty that doesn’t exist.
Point that effort at the page instead. Add something new that the other results don’t have.
That’s the test that matters, and it’s one no watermark can fail for you.
Explore more on
Editorial disclosure
Contributing authors are chosen for their expertise and work under the oversight of the editorial staff. Search Engine Land is owned by Semrush. The contributor was not asked to mention Semrush; the opinions expressed are their own.
About the author


